AI Agents

Agent fundamentals, multi-agent systems, agent memory, harnesses, and the MCP tooling layer behind autonomous LLM agents.

ReAct and the Birth of Agent Memory: Why Reasoning Is Memory Creation

ReAct and the Birth of Agent Memory: Why Reasoning Is Memory Creation

Yao, S., Zhao, J., Yu, D., Du, N., Shafran, I., Narasimhan, K., Cao, Y.

ICLR 2023

A reinterpretation of ReAct through the lens of memory systems. Most engineers see ReAct as reasoning plus acting. The deeper contribution is that it introduced explicit working memory into LLM agents — every thought is a state update, every observation is a memory write, and the evolving context becomes the foundation for all modern agent memory architectures from MemGPT to Letta to SimpleMem.

  • First paper to introduce working memory into LLM agents via accumulated thought-action-observation context
  • Every reasoning trace is a state transition — thoughts are memory writes, not just text generation
  • Augmented action space A-hat = A union L treats language itself as a state-modifying operation
  • Direct intellectual ancestor of MemGPT, Letta, SimpleMem, Mem0, and all modern agent memory systems
  • 71% success on ALFWorld vs 37% for agents trained on 100,000+ expert demonstrations — memory enables this
AI Agents Memory Systems Working Memory ReAct Tool Use Agent Architecture State Management Production Systems MCP LangGraph DSPy Amazon Bedrock Tool Calling
SWiRL: Step-Wise Reinforcement Learning for Multi-Step Reasoning and Tool Use

SWiRL: Step-Wise Reinforcement Learning for Multi-Step Reasoning and Tool Use

Goldie, A., Mirhoseini, A., Zhou, H., Cai, I., Manning, C. D.

arXiv:2504.04736

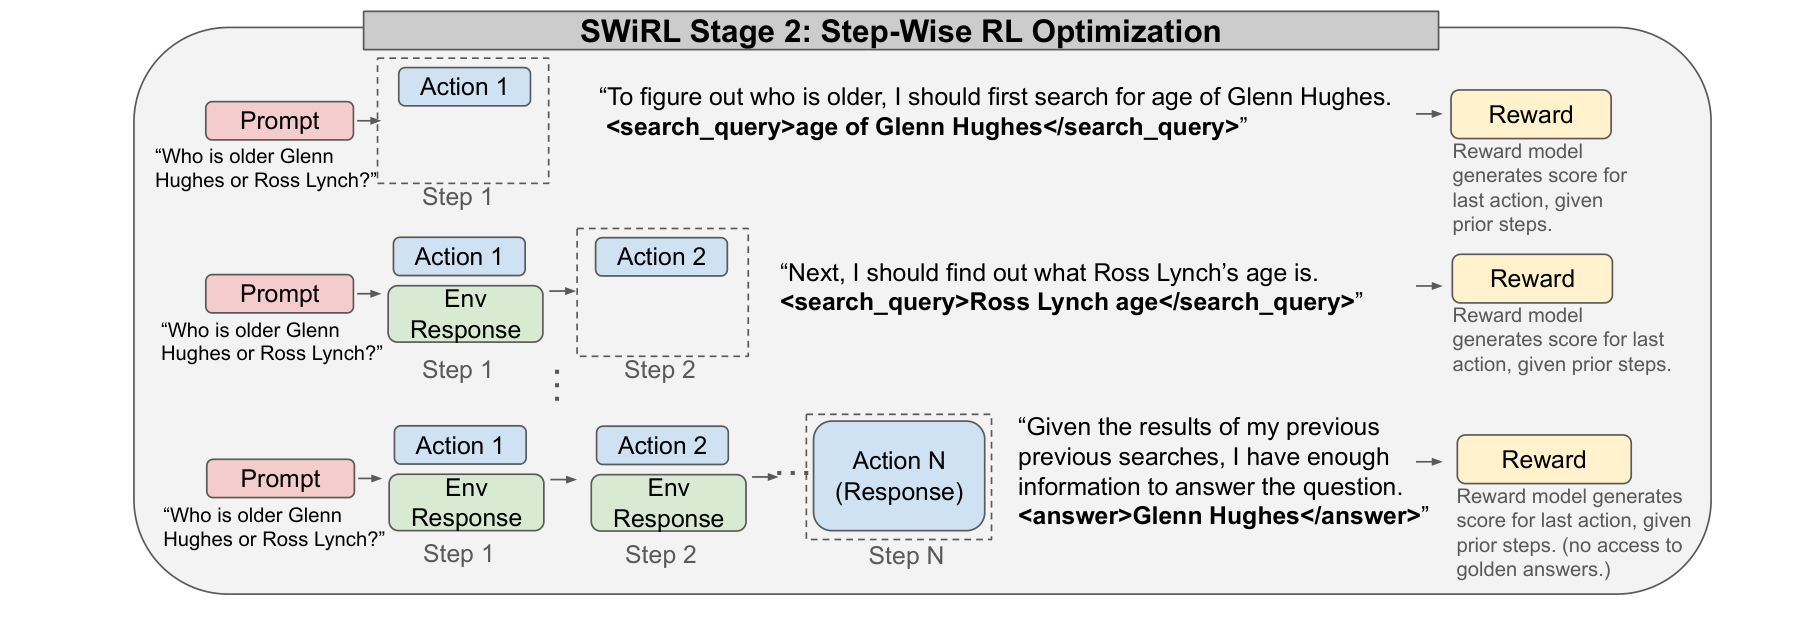
An engineering deep-dive on step-wise reinforcement learning (SWiRL): building the two-stage pipeline that turns multi-step agent trajectories into process-filtered, step-level training data for reasoning and tool use.

  • SWiRL is a training pipeline, not a new optimizer — it turns long agent trajectories into step-level state–action units that RL can actually learn from
  • Two decoupled stages: Stage 1 generates and filters multi-step trajectories with live tools; Stage 2 replays the saved states offline and applies step-wise RL
  • Process filtering keeps a step if it was reasonable given its state — no golden answer required — so trajectories that end wrong but reason well stay in the training set
  • A reward lands on every action, R(a | s), not once at the end of the episode; the objective is expected step-wise reward optimized by policy gradient over one policy
  • Offline replay means tools run only during generation — training never depends on tool latency, rate limits, or nondeterminism
AI Agents Multi-Step Reasoning Planning Step-Wise Reinforcement Learning SWiRL Multi-Step RL Process Filtering Synthetic Data Generation Offline RL Tool Use Policy Gradient Reward Model Trajectory Decomposition LLM Agents
SPRINT: Interleaved Planning and Parallelized Execution in Reasoning Models

SPRINT: Interleaved Planning and Parallelized Execution in Reasoning Models

Biju, E., Talaei, S., Huang, Z., Pourreza, M., Mirhoseini, A., Saberi, A.

arXiv 2025 · Stanford / Microsoft / Google

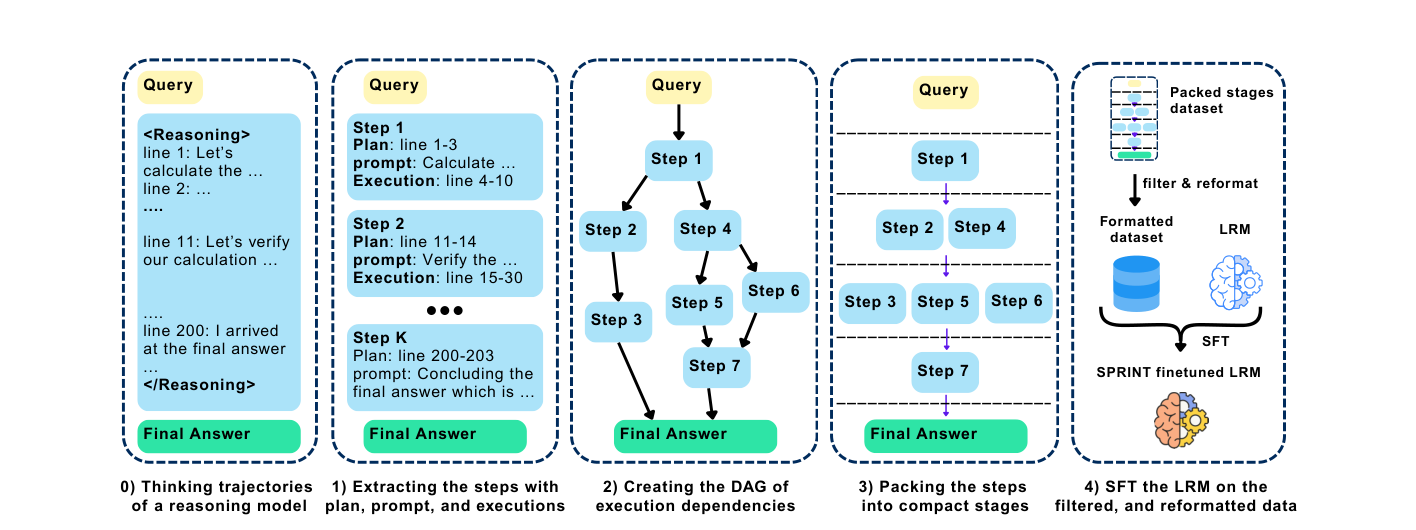
An engineering deep-dive on SPRINT: post-training a reasoning model to emit an interleaved plan/parallel-execution trajectory, and the data-curation pipeline (step extraction → dependency DAG → stage packing → SFT) that teaches it where reasoning can branch.

  • SPRINT is a post-training (SFT) framework, not a new decoding kernel — it teaches a reasoning model to emit a plan → parallel-execution → sync trajectory instead of one long serial chain
  • The parallelism lives at the reasoning/task level: a planner proposes independent subtasks, a pool of executors (the same model) runs them concurrently, results sync back into a shared context
  • Training data is manufactured, not collected: ordinary DeepSeek-R1 traces are split into plan/execution steps, wired into a dependency DAG, and packed into stages — parallelism falls out of the DAG, never from textual adjacency
  • The optimized quantity is sequential tokens (the critical-path length), not total tokens — SPRINT can generate MORE total tokens while cutting the longest dependency chain
  • There is no reward model. The correctness filter only selects which raw traces to curate; the training objective is plain supervised next-token loss on the restructured sequence
AI Agents Multi-Step Reasoning Planning SPRINT Parallel Reasoning Reasoning Models LRM Inference-Time Compute Dependency DAG Interleaved Planning Supervised Fine-Tuning Sequential Tokens Latency Data Curation DeepSeek-R1

Harness Engineering: Inside the Runtime of Production Coding Agents (and How to Build One)

Barbaste, P., Darrigol, T., Vu, G., Wiltberger, T.

arXiv:2609.00006 · Inclusive Brains / Wavestone AI Lab

Harness engineering via source-code case studies of Claude Code, Codex, Gemini CLI, OpenHands and 7 more coding agents, plus a tested Python reference harness.

  • Agent = Model + Harness: the harness is the runtime that turns model output into reliable work - loop, tools, context, safety, orchestration, extensibility
  • Eleven production coding harnesses, read at source level, all implement the same seven subsystems - from a ~100-line floor (Mini-SWE-Agent) to million-line platforms (Codex)
  • Loop sophistication does not predict benchmark results in this corpus; most production code buys safety, recovery, extensibility, UX and transport
  • Parallel tool execution needs concurrency semantics: declared safety, declared resources, ordered results
  • No studied harness imports an agentic framework in its runtime, and none retrieves code with embeddings
  • Includes a stdlib-only Python reference harness with 55 passing tests: scheduler, policy engine, verify-on-stop, event log, compaction, sub-agents, deferred tools
Harness Engineering AI Agents Coding Agents Agent Harness Claude Code Codex CLI Gemini CLI OpenHands Aider Agent Loop Tool Calling Context Engineering Policy-as-Code Sandboxing Event Sourcing Multi-Agent MCP Agent Skills

Toolformer: How a Language Model Teaches Itself to Use Tools

Schick, T., Dwivedi-Yu, J., Dessì, R., Raileanu, R., Lomeli, M., Zettlemoyer, L., Cancedda, N., Scialom, T.

NeurIPS 2023 · arXiv 2302.04761

An engineering dissection of Toolformer — a language model that teaches itself when and how to call external APIs (calculator, QA, search, translation, calendar) in a self-supervised way, with no human tool-use annotations. Covers the sample-execute-filter-finetune loop, the perplexity-based filtering criterion that decides which API calls are actually useful, the API-call token format that needs no vocabulary change, inference-time API interruption, the finding that tool use emerges only above ~775M parameters, and the honest limits: no chained or interactive tool use.

  • Teaches tool use self-supervised: a model annotates a plain-text corpus with candidate API calls, keeps only the ones that measurably help predict the following tokens, and fine-tunes on the result — no human tool-use labels
  • The filtering criterion is a loss comparison: keep an API call only if seeing its input AND result lowers cross-entropy on future tokens by at least a threshold versus not calling or calling blind
  • API calls are encoded with ordinary tokens ([, ], ->) so no vocabulary change is needed, and at inference the decoder is interrupted at the -> token to run the tool and splice in the result
  • Tool use is emergent: a 6.7B GPT-J beats the 25x-larger GPT-3 175B on factual and math tasks, but the ability to use tools well only appears above ~775M parameters
Toolformer Tool Use Function Calling Self-Supervised LLM Agents APIs In-Context Learning GPT-J Augmented LMs

LLM-Based Agents: The Brain–Perception–Action Framework

Xi, Z., Chen, W., Guo, X., He, W., Ding, Y., Hong, B., Zhang, M., Wang, J., Jin, S., Zhou, E., et al. (Fudan NLP Group)

arXiv 2309.07864

An engineering dissection of 'The Rise and Potential of LLM-Based Agents: A Survey.' Instead of summarizing 86 pages, it extracts the one thing an engineer can build on: the Brain–Perception–Action framework that decomposes an LLM agent into a controller (the LLM), an input space (perception), and an output space (action). Covers the perceive-think-act loop, the brain's memory and reasoning/planning typology, the multi-agent taxonomy (disordered vs ordered cooperation, adversarial debate), the two human-agent paradigms (instructor-executor, equal partnership), and the open problems that still gate real deployment.

  • Decomposes any LLM agent into three modules — Brain (the LLM controller: memory, knowledge, reasoning, planning), Perception (expands the input space beyond text to multimodal), and Action (expands the output space to tools and embodied action)
  • Frames the agent as a perceive-think-act loop that continuously takes feedback from its environment — the same loop ReAct, Toolformer, and tool-calling systems each implement a slice of
  • Organizes multi-agent systems into a clean taxonomy: cooperative (disordered free-for-all vs ordered pipelines like MetaGPT) and adversarial (debate and self-play that sharpen answers)
  • Names the failure modes that matter in production — cascading hallucination amplified by agent-to-agent interaction, the virtual-to-physical gap, and the difficulty of coordinating many agents into genuine collective intelligence
LLM Agents AI Agents Agent Architecture Multi-Agent Systems Perception Planning Memory Tool Use Survey Agent Fundamentals
LLMCompiler: Why DAG Planning Is the Future of Tool-Calling AI Agents

LLMCompiler: Why DAG Planning Is the Future of Tool-Calling AI Agents

Kim, S., Moon, S., Tabrizi, R., Lee, N., Mahoney, M. W., Keutzer, K., Gholami, A.

ICML 2024

A compiler-inspired orchestration framework that automatically identifies parallelizable LLM function calls, executes them concurrently via a DAG-based planner, and delivers up to 3.7x lower latency and 6.7x cost reduction over sequential ReAct-style execution. This architectural shift from sequential reasoning to parallel compilation fundamentally changes how production AI agents should orchestrate tool use.

  • Reduces multi-tool agent execution from O(N) sequential LLM calls to 2 LLM calls regardless of task count
  • DAG-based planning with dependency resolution enables true parallel tool execution without sacrificing correctness
  • Task Fetching Unit provides LLM-free scheduling — pure orchestration logic with zero inference cost
  • 3.74x latency speedup and 6.73x cost reduction on Movie Recommendation vs ReAct
  • Dynamic replanning loop handles workloads that cannot be statically compiled upfront
AI Agents Tool Use Parallel Execution DAG Planning LLM Orchestration Function Calling Production Systems Compiler Theory

SimpleMem: Efficient Lifelong Memory for LLM Agents — Semantic Lossless Compression, Synthesis & Intent-Aware Retrieval

Liu, J., Su, Y., Xia, P., Han, S., Zheng, Z., Xie, C., Ding, M., Yao, H.

arXiv 2601.02553

An engineering dissection of SimpleMem — how semantic lossless compression, online synthesis, and intent-aware retrieval give LLM agents efficient lifelong memory at 30x lower token cost.

  • Reframes agent memory as a three-stage pipeline: Semantic Structured Compression → Online Semantic Synthesis → Intent-Aware Retrieval Planning, built on 'semantic lossless compression'
  • Distills raw dialogue into multi-view indexed memory units (semantic embedding + lexical keywords + symbolic metadata) with pronouns resolved and time anchored to absolute ISO-8601
  • Reports +26.4% average F1 over Mem0 on LoCoMo while cutting inference-time token consumption up to 30x versus full-context serving
  • Maps every stage to the real released code (aiming-lab/SimpleMem): MemoryBuilder, HybridRetriever, the MemoryEntry schema, LanceDB + Tantivy storage — and flags where the paper's formalism and the shipped engine diverge
SimpleMem Agent Memory Lifelong Memory LLM Agents Semantic Compression Memory Consolidation Adaptive Retrieval Hybrid Retrieval RAG LoCoMo Token Efficiency