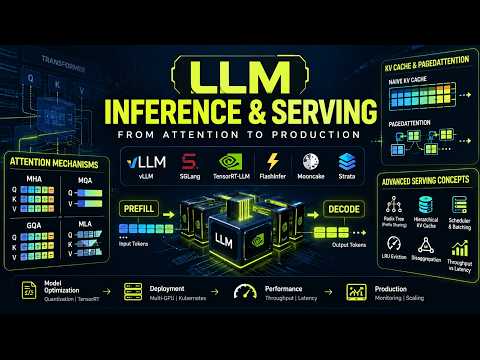
LLM Inference & Serving Deep Dive: vLLM, SGLang, TensorRT-LLM & KV Cache Optimization
Oct 2026
How modern inference engines optimize memory, cut latency, and maximize throughput when serving LLMs at scale. Covers attention variants (MHA, MQA, GQA, MLA), KV cache sizing, prefill vs. decode, vLLM PagedAttention, SGLang RadixAttention and prefix caching, TensorRT-LLM, FlashInfer, continuous batching, Mooncake's disaggregated KV cache, Strata's hierarchical KV cache, prefill/decode disaggregation, quantization, and multi-GPU distributed serving.
Watch Session