Mistral's Sovereign Appeal: Mistral Large 4 "le chonk"
Mistral Large 4 is Mistral’s largest and most capable model, and the most powerful AI model a European company has released so far. On independent benchmarks, it lands close to OpenAI’s GPT-6 Luna.
It trails cheaper open-weight models from China but beats every open-weight model from the United States. And it leads all models at finding and repairing one class of software vulnerabilities.
What’s New in Mistral Large 4
Mistral has opened API preview access to Mistral Large 4, nicknamed “le Chonk.” It says the weights will be released by the end of this month.
Until then, selected companies, partners and government agencies get a version with fewer safeguards and extra cybersecurity capabilities.
- Input/output: text and images in (up to 1 million tokens), text out
- Architecture: mixture of experts with 1.05 trillion parameters, 52 billion active per token, plus a 1.6-billion-parameter vision encoder
- Features: reasoning (off or high via the API), function calling, tool use, regional inference
- Performance: the highest-scoring model from outside China and the US on the Artificial Analysis Intelligence Index (38), and first among publicly available models on CyberGym-E2E-AA, a test of finding and fixing memory-safety bugs (82%)
- Availability and price: public preview through the Mistral Studio API at $1.36 / $0.14 / $4.18 per million input / cached / output tokens. It’s half price for the first two weeks after launch, and half price for batched requests
- Weights and licence: not yet released, and the licence hasn’t been announced
- Undisclosed: knowledge cutoff, output limit, architecture details, and the specific training data and methods
How Mistral Large 4 Works
Mistral has said little about the architecture so far, and promises more detail once the weights are out. What we do know: it pretrained the model from scratch, then fine-tuned it with supervised learning followed by reinforcement learning (RL).
Training Data and Compute
Mistral trained the model on 3,800 GPUs in its own data centres. The training data mixed publicly available web data, licensed datasets, and inputs and outputs from users of Mistral’s products who opted into data sharing.
That data spanned more than 160 languages, including every official language of the European Union.
One RL Run, Many Kinds of Task
A single RL run mixed very different tasks: single-turn chat, science problems, safety, factual accuracy and long-running tool use. The tasks ran in environments that shared resources such as code sandboxes, web search and APIs.
The reward depended on the task. It could come from unit tests, reward models, language-model judges, or static checks that inspect code without running it.
Training That Hasn’t Finished
The RL run behind the API preview is still going. Many copies of the model attempt tasks in parallel, and the model gets updated as results come in, rather than waiting for each round of attempts to finish.
That means the model you call today is a snapshot. Mistral says it expects large, rapid improvements in the weeks and months ahead.
Mistral Large 4 Performance and Capabilities
The Mistral Large 4 preview outscores every other model built outside China and the US on Artificial Analysis’ Intelligence Index. A handful of open-weight models score higher, all from Chinese companies, but it’s ahead of every US-based open model. Its strongest results are in cybersecurity.
Artificial Analysis Intelligence Index
The Intelligence Index is a weighted average of 10 evaluations covering math, science, coding and reasoning. With reasoning on, Mistral Large 4 ties GPT-6 Luna and trails three cheaper open-weight models.
| Model | Intelligence Index | Cost per task |
|---|---|---|
| MiMo-V2.6-Pro | 46 | $0.13 |
| GLM-5.3-Flash | 42 | $0.25 |
| DeepSeek V4.1 Flash (max reasoning) | 39 | $0.27 |
| Mistral Large 4 (reasoning) | 38 | $1.13 |
| GPT-6 Luna | 38 | $0.07 |
The cost column is the catch. Mistral Large 4 gets the same score as GPT-6 Luna at about 16 times the cost per task, and all three models ahead of it are cheaper too.
Artificial Analysis Cyber Index
The Cyber Index measures how well models find and fix security vulnerabilities in code repositories. Among publicly available models, Mistral Large 4 ties GLM-5.3-Flash and trails only two others.
| Model | Cyber Index | Cost per task |
|---|---|---|
| GPT-6 Sol Daybreak Blue (max reasoning, selected organisations only) | 69% | $1.77 |
| Grok 4.7 (xhigh reasoning) | 56% | $11.67 |
| MiMo-V2.6-Pro (reasoning) | 56% | $0.18 |
| Mistral Large 4 (reasoning) | 50% | $2.79 |
| GLM-5.3-Flash (reasoning) | 50% | $0.32 |
On one component of the index, CyberGym-E2E-AA, Mistral Large 4 solves 82% of tasks. These involve memory-safety bugs in popular open-source C and C++ projects. That’s the highest score of any publicly available model, behind only the restricted GPT-6 Sol Daybreak Blue (93%).
What Mistral’s Own Charts Show
Mistral’s launch charts tell a rosier story than the full leaderboards above, because Mistral picked the rivals. The charts below are all from Mistral’s launch post. Most of the scores come from third-party evaluators (Artificial Analysis, Vals.ai, Surge AI and Lakera). In every chart, the orange bar is Mistral Large 4 Preview.
Cybersecurity: The Headline Result
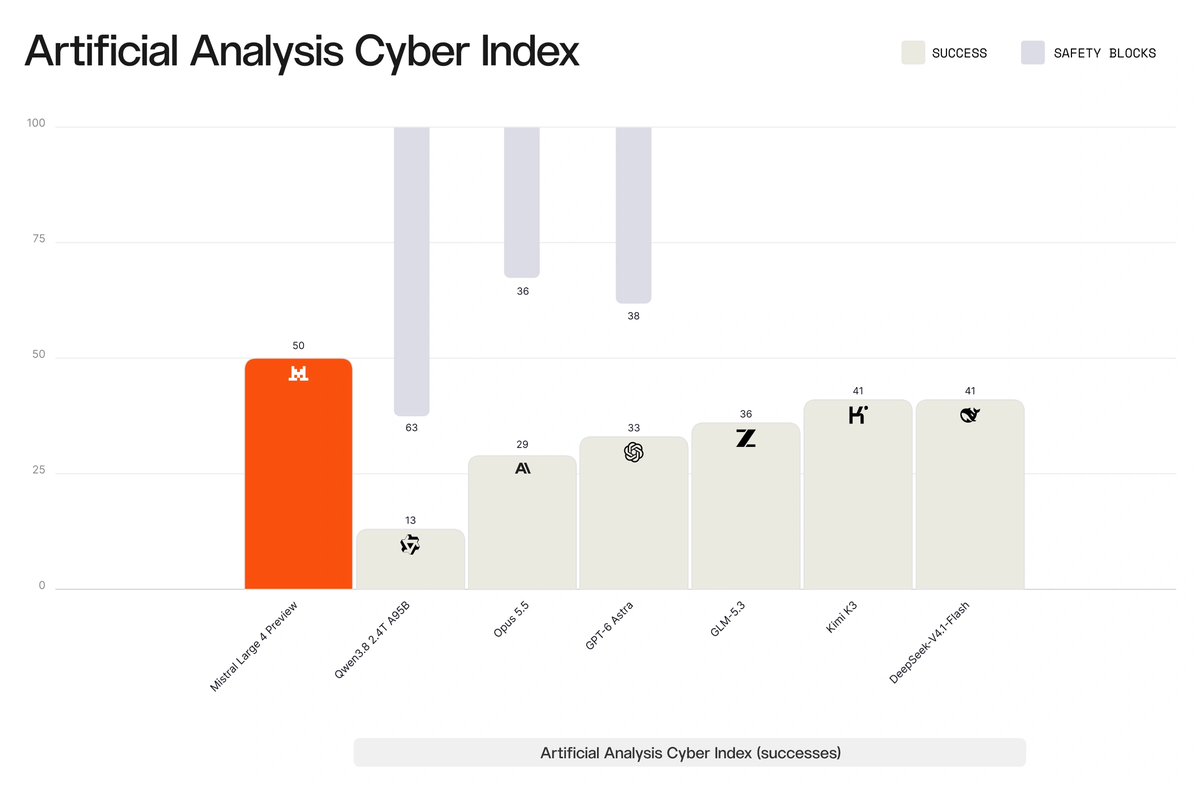 Artificial Analysis Cyber Index, as charted by Mistral: ML4 has the top bar at 50, but the chart leaves out Grok 4.7, MiMo-V2.6-Pro and GPT-6 Sol Daybreak Blue, which all score higher. The bars hanging from the top are safety blocks: Qwen3.8 (63), GPT-6 Astra (38) and Opus 5.5 (36) refused many of the tasks.
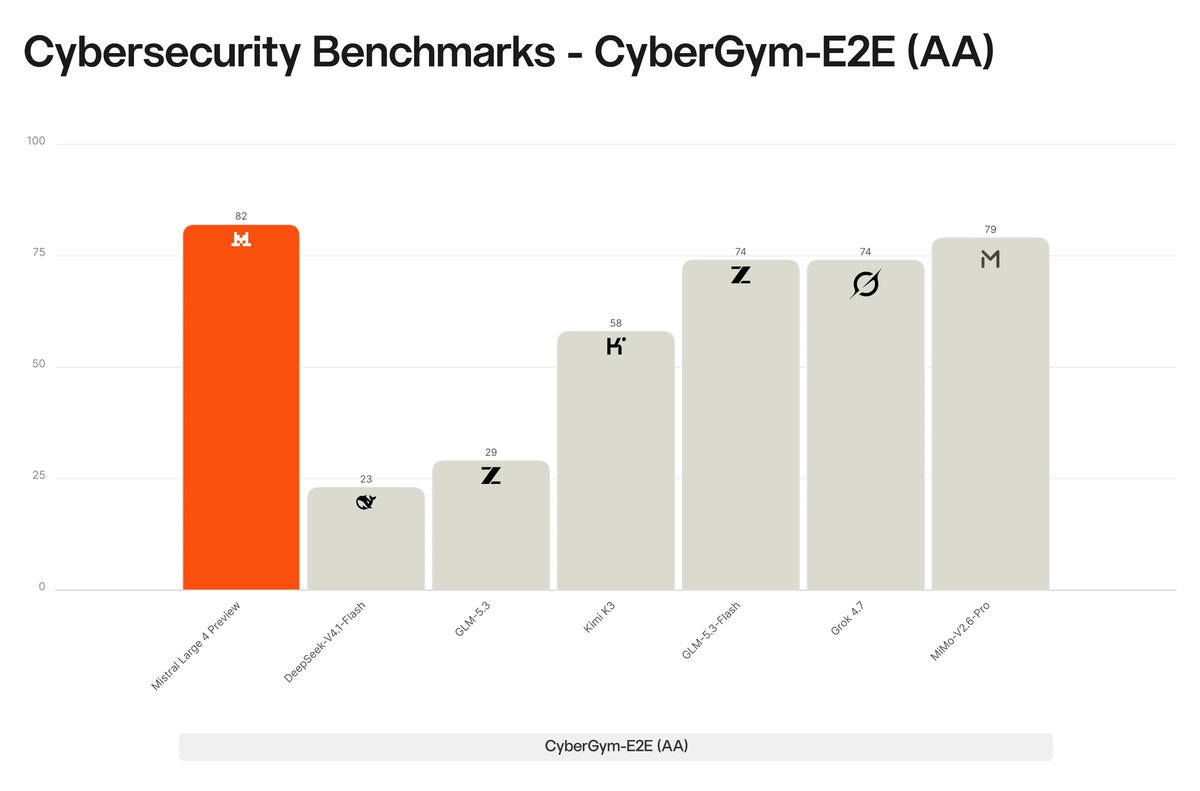 CyberGym-E2E: reproduce a real vulnerability, then patch it. ML4 scores 82, the top score on the chart.
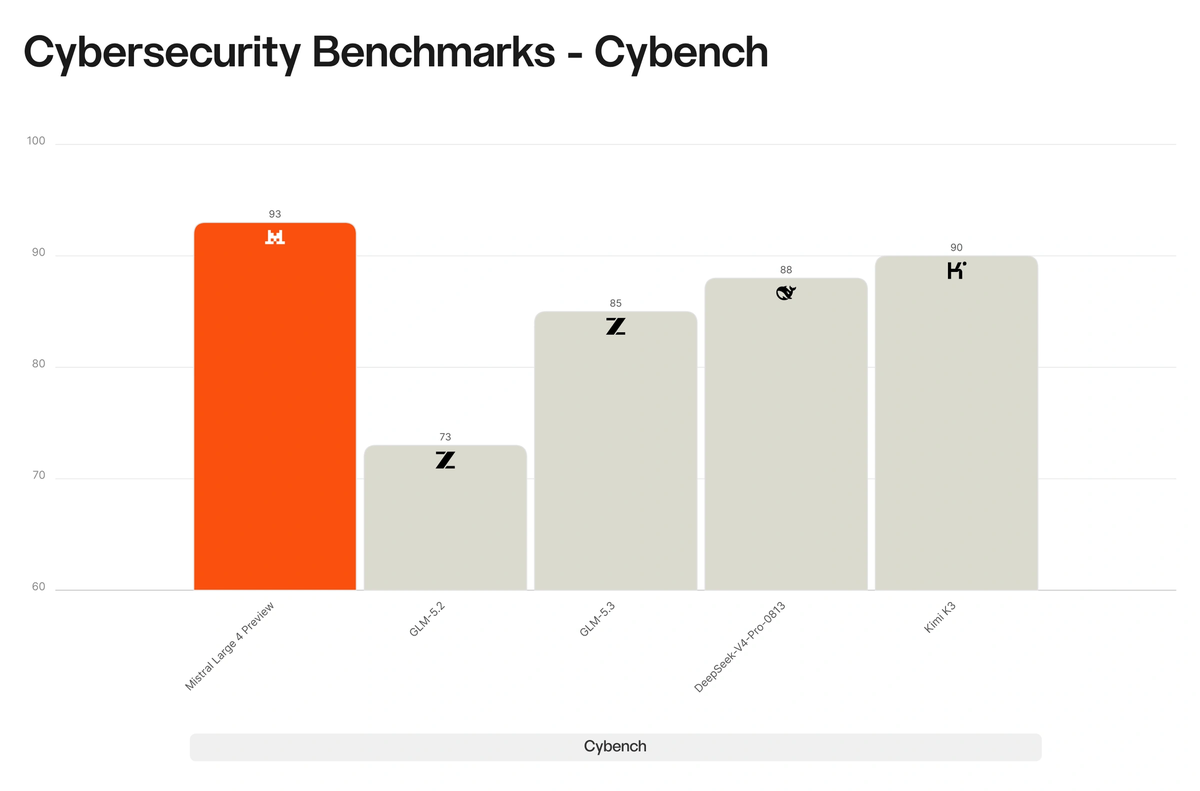 Cybench: 40 capture-the-flag challenges from security competitions. ML4 solves 93%.
This is where Mistral Large 4 stands out most. Mistral says it ranks in the top five models on the Artificial Analysis Cyber Index and leads every open-weight model built outside China by a wide margin.
The interesting part is why it wins. Mistral says closed models like Claude Opus 5.5 and GPT-6 Astra score near zero on the reproduce-and-patch test because they refuse to do it. But proving a flaw is real is often the first step in fixing it. That’s the sovereign AI pitch in one chart: a model you can host yourself, under your own policies.
Agentic Coding
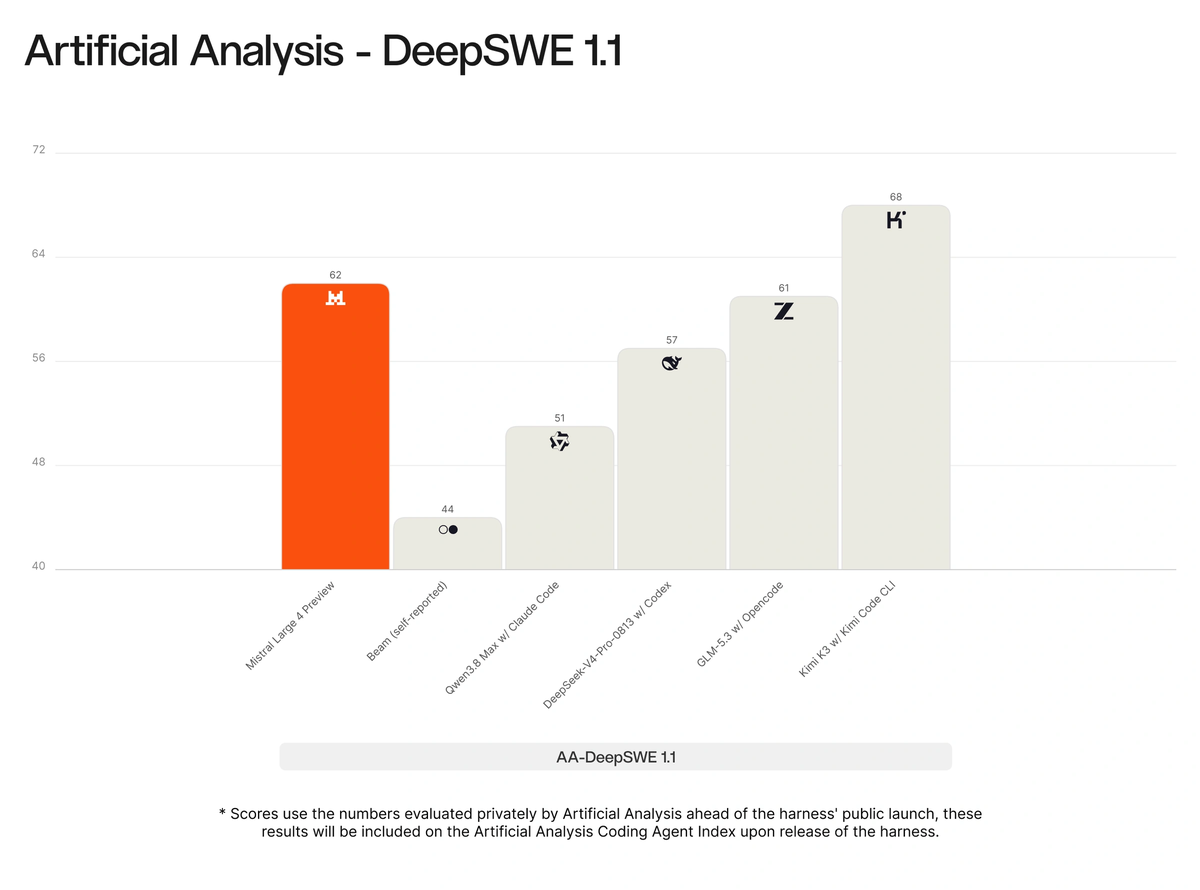 DeepSWE 1.1: ML4 scores 62, second only to Kimi K3 (68).
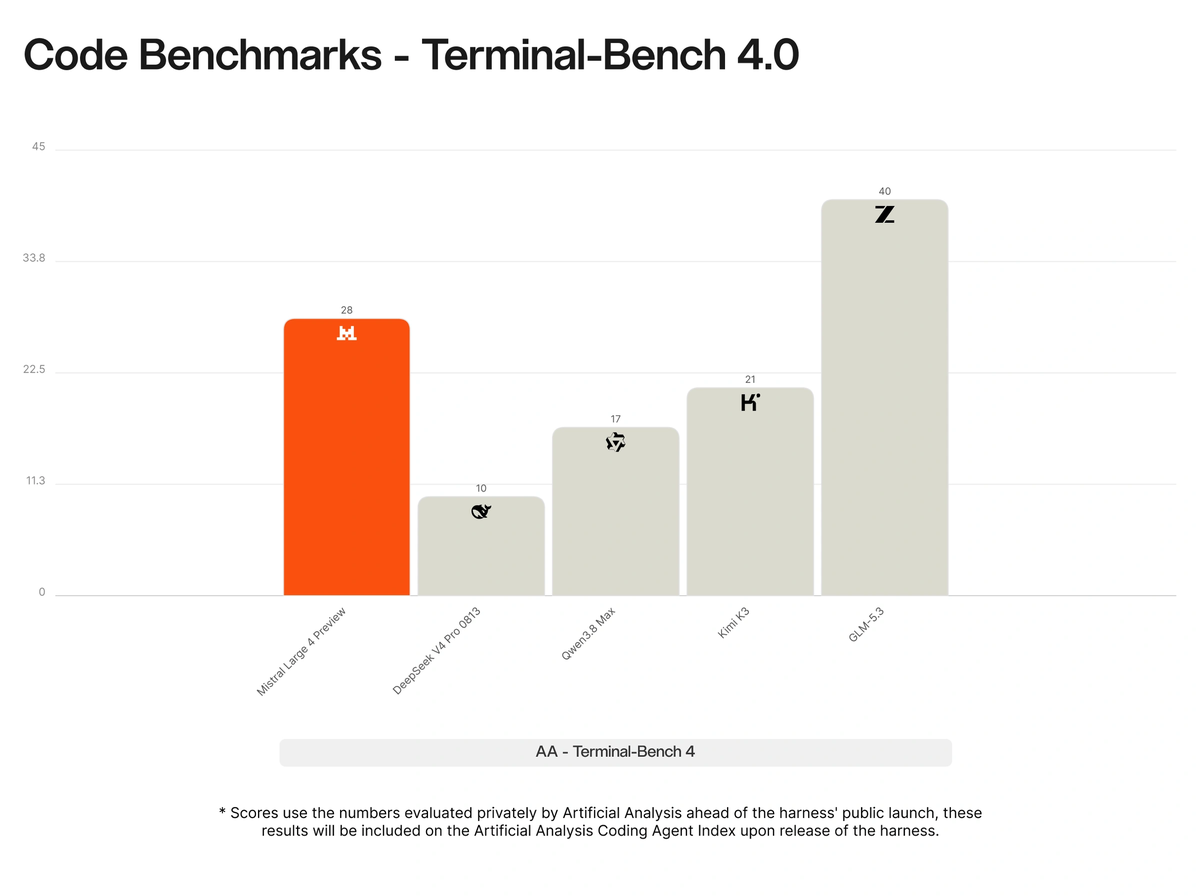 Terminal-Bench 4.0: ML4 scores 28, well behind GLM-5.3 (40).
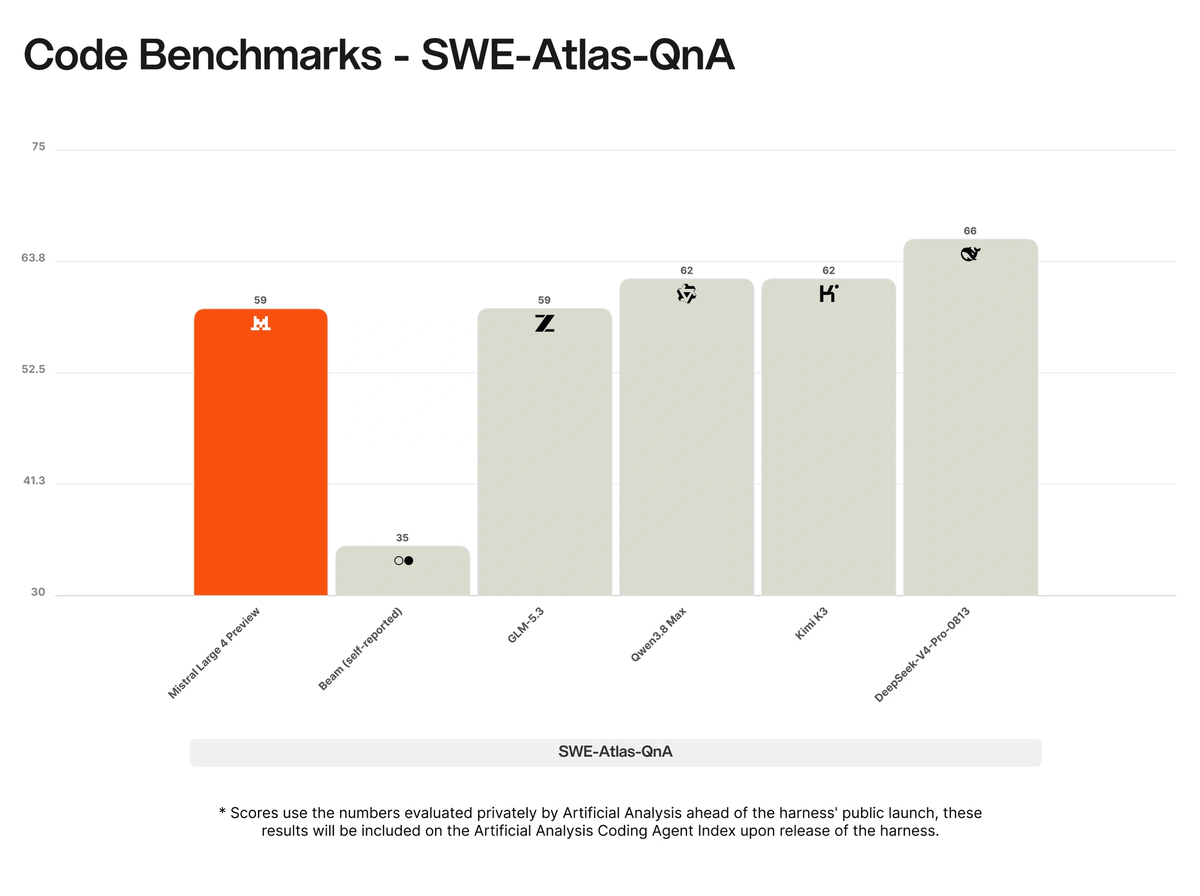 SWE-Atlas-QnA: ML4 scores 59, tied with GLM-5.3 and behind three rivals.
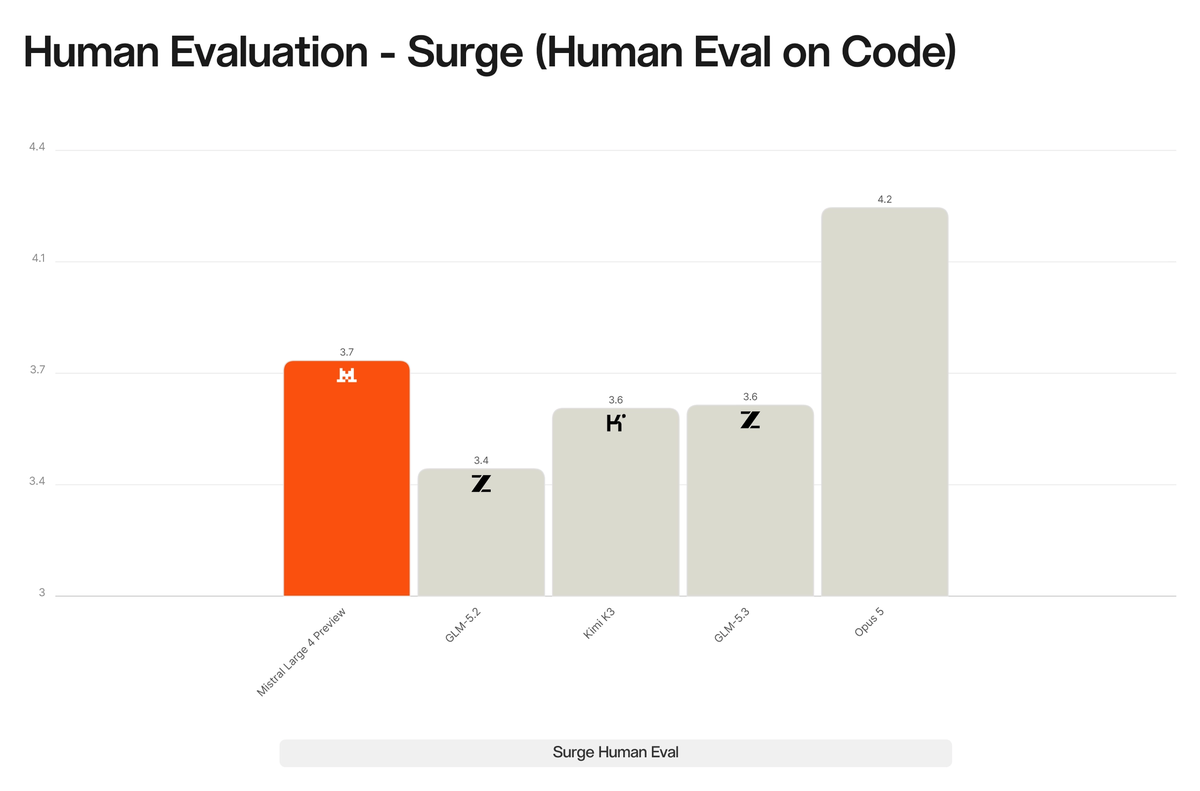 Surge AI blind human evaluation of code quality (1–5 scale): ML4 rated 3.74, behind only Claude Opus 5 (4.22).
Mistral reports 61.7% on DeepSWE 1.1, 59.4% on SWE-Atlas-QnA and 28.3% on Terminal-Bench 4, for a combined Coding Agent Index score of 49.8. That puts it ahead of DeepSeek V4 Pro 0813 and Qwen3.8 Max overall.
Read the charts closely, though. Mistral Large 4 doesn’t top any of the three coding benchmarks. It’s a strong all-rounder, not the best coding model. The Artificial Analysis coding scores were run privately before the test harness went public.
Agentic Workflows
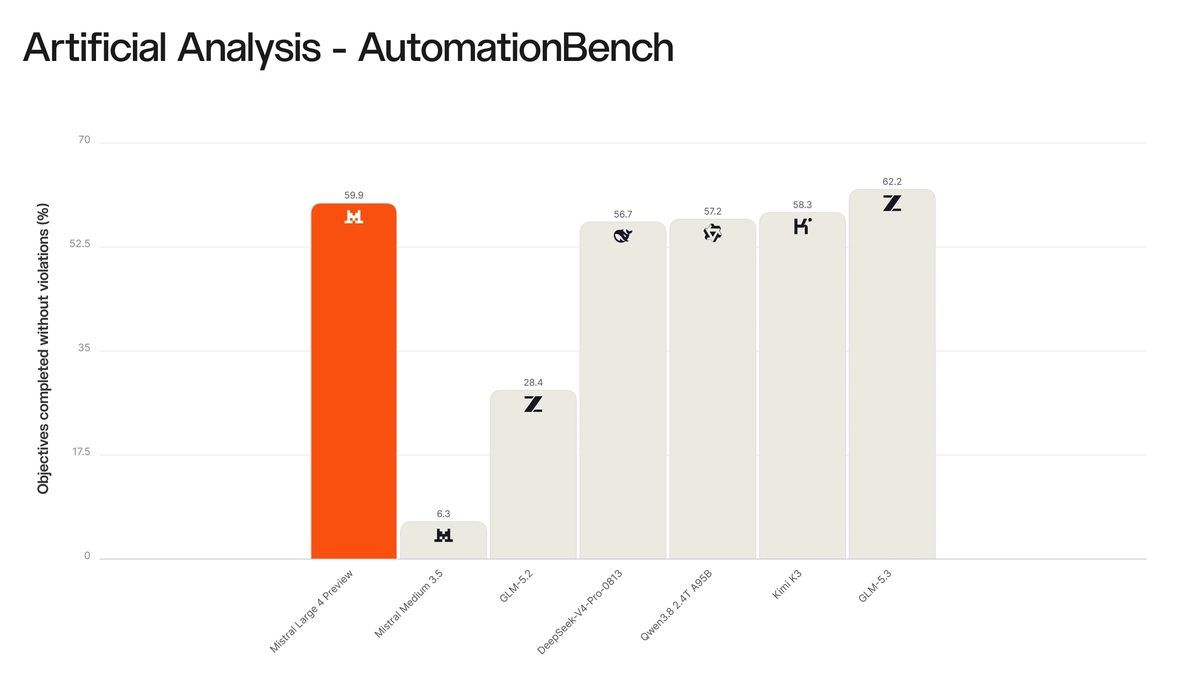 AutomationBench: 657 business workflows across Gmail, Google Sheets, Slack and Salesforce. ML4 completes 59.9%, a huge jump from Mistral Medium 3.5 (6.3%).
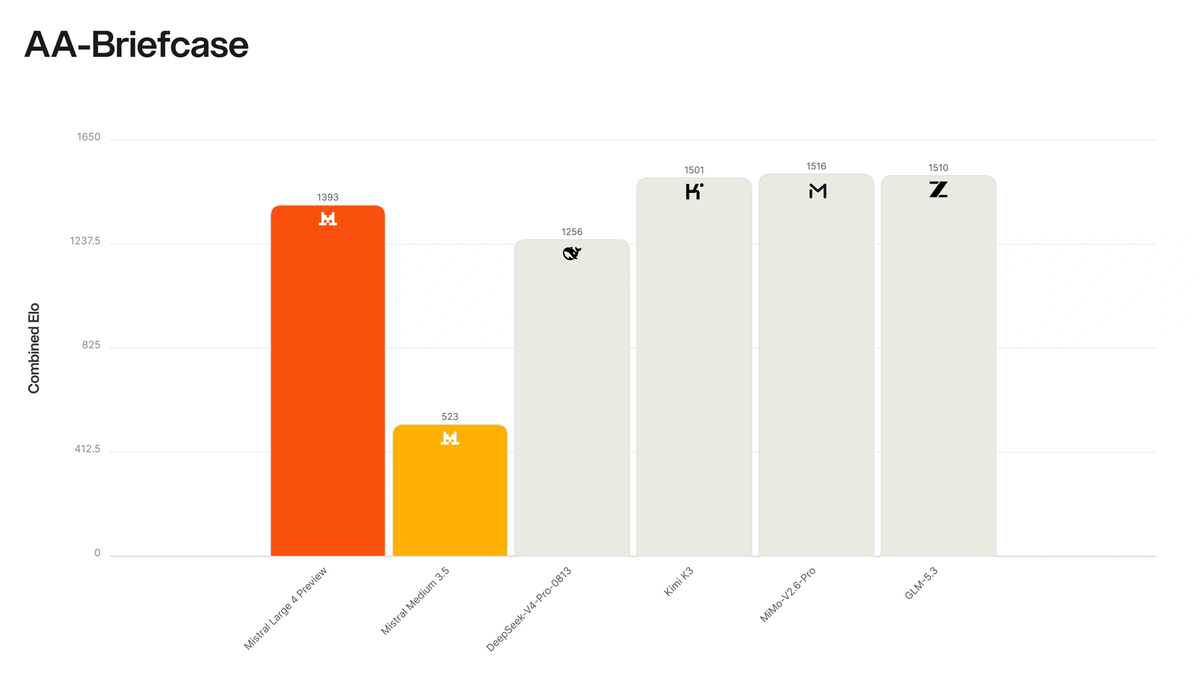 AA-Briefcase: long-horizon knowledge work producing spreadsheets, slides and PDFs. ML4 reaches 1,393 Elo.
The jump from Mistral’s previous generation is the real story here. On both charts, Mistral Large 4 is several times better than Mistral Medium 3.5.
Against the field, it’s mid-pack. GLM-5.3 leads AutomationBench, and three rivals sit more than 100 Elo points ahead on AA-Briefcase.
Multimodal and Visual Grounding
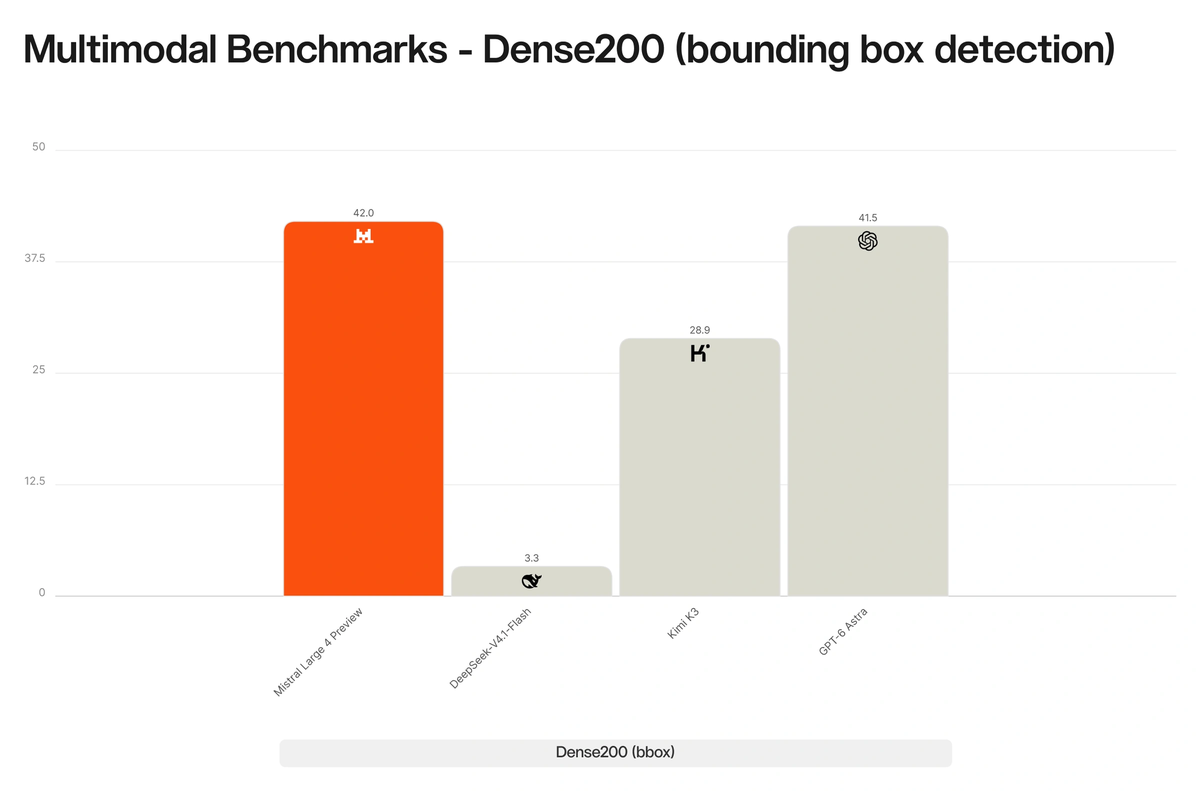 Dense200 (bounding box detection): ML4 edges out closed GPT-6 Astra, 42.0 to 41.5.
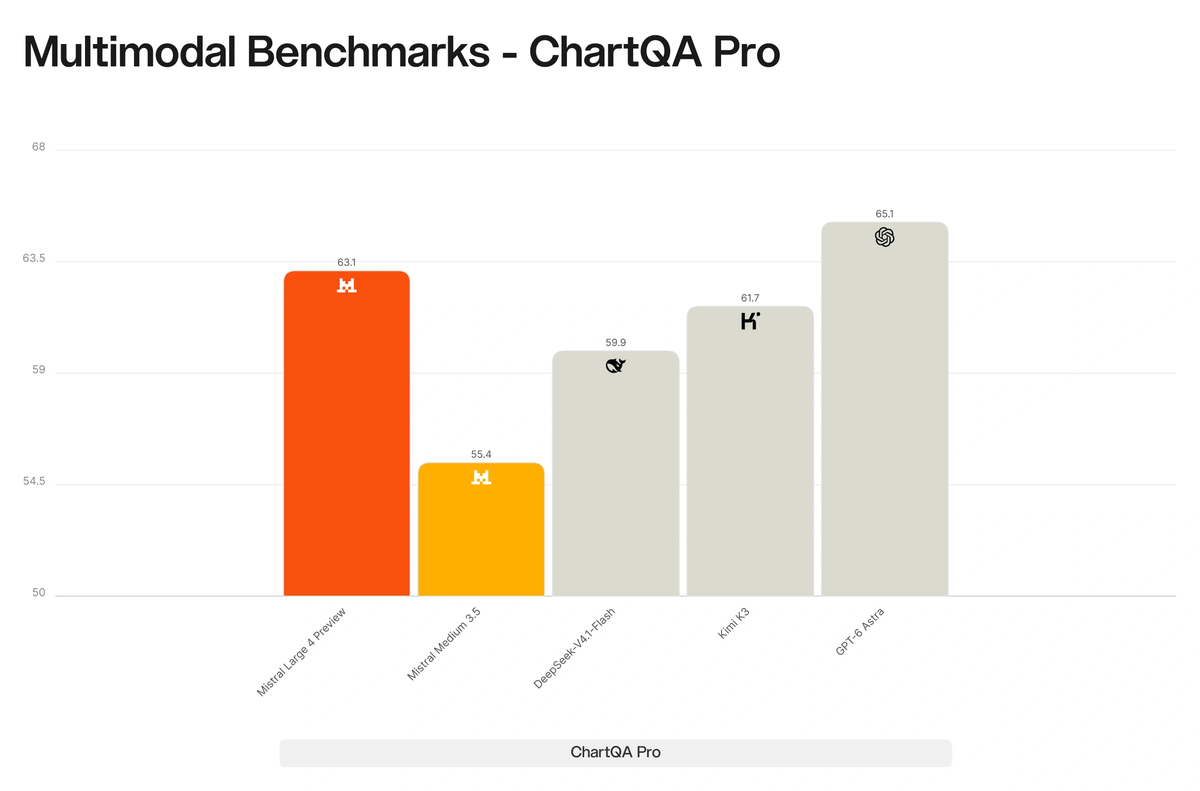 ChartQA Pro: ML4 scores 63.1, the best open-weight model on the chart, behind GPT-6 Astra (65.1).
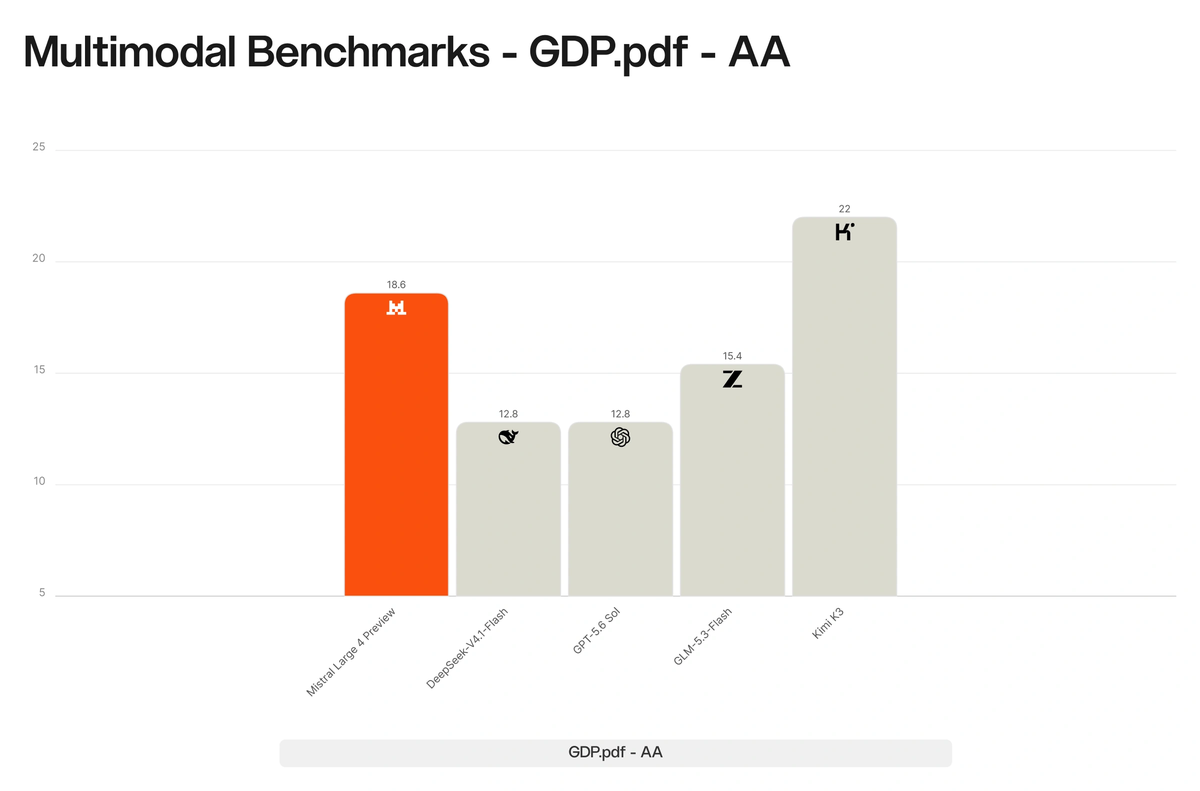 GDP.pdf: evidence retrieval from PDFs. ML4 scores 18.6, second to Kimi K3 (22).
Visual grounding means pointing to exactly where something is in an image, not just describing it. It’s the one area where Mistral Large 4 beats a frontier closed model on Mistral’s charts.
Mistral pairs grounding with agentic tool use: scanning gigapixel satellite images for disaster response, or zooming into engineering drawings to check mechanical parts.
Science and Math
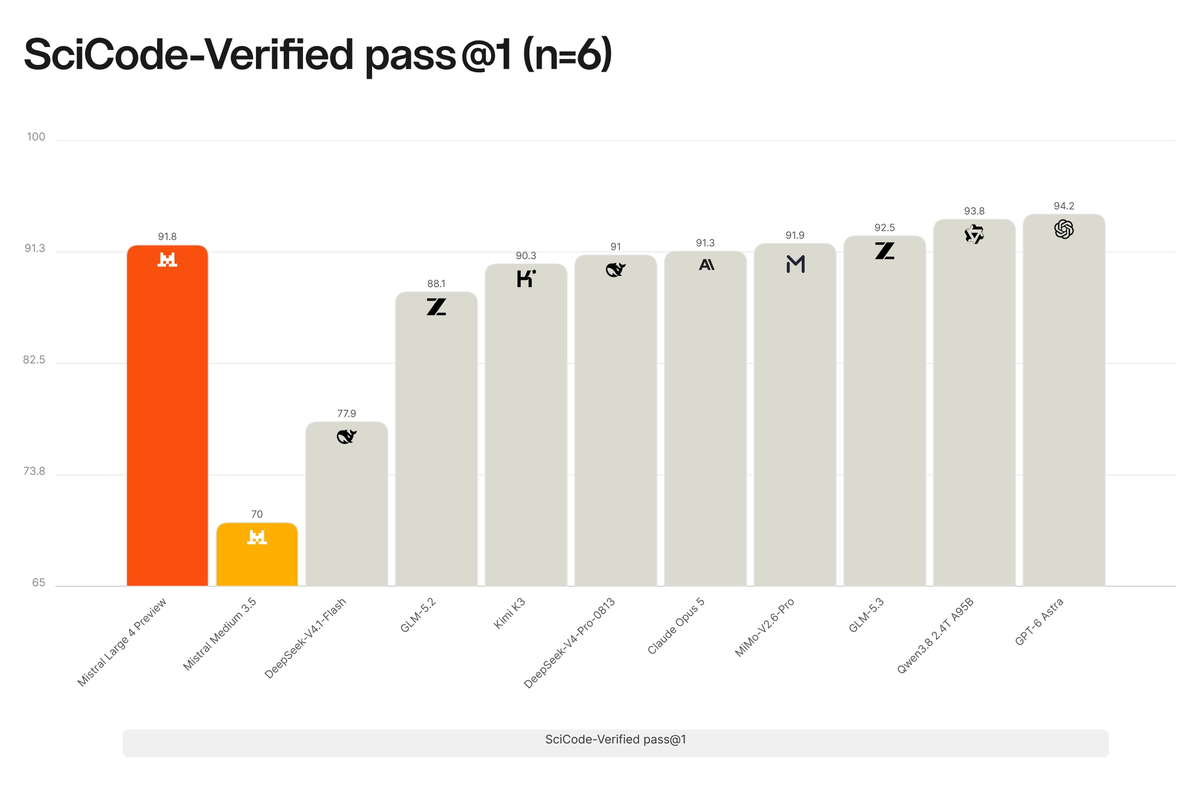 SciCode-Verified pass@1: ML4 scores 91.8. The top of the chart is tightly packed, with five models between 91.8 and 94.2.
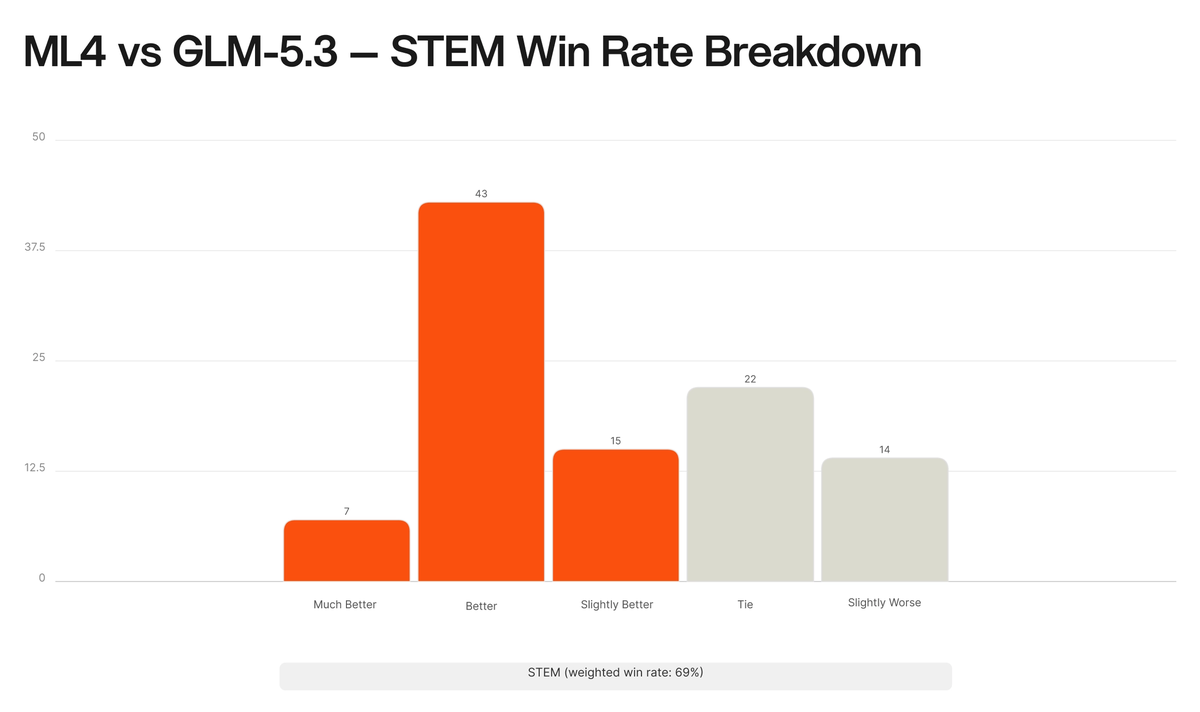 Internal STEM evaluation (math and physics) against GLM-5.3: a 69% weighted win rate for ML4.
SciCode-Verified tests whether a model can turn physics, math, materials science and biology workflows into working code. Mistral calls Mistral Large 4 state of the art among open-weight models here, but on its own chart, Qwen3.8, GLM-5.3 and MiMo-V2.6-Pro score slightly higher.
The math result is stronger. In Mistral’s internal head-to-head, graders rated it better than GLM-5.3 on 65% of STEM tasks, and Mistral says it can write a full Hartree–Fock chemistry simulation in one shot.
Knowledge Work: Finance and Legal
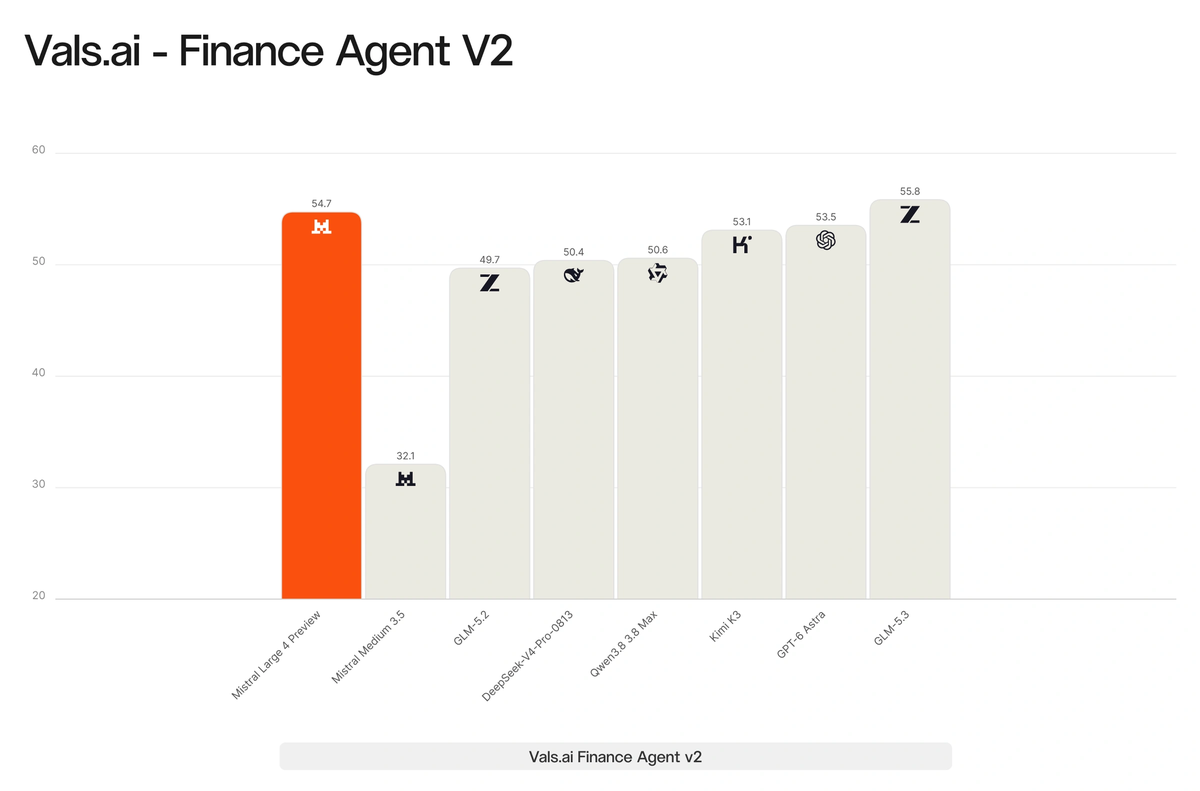 Vals.ai Finance Agent v2: ML4 scores 54.7, ahead of GPT-6 Astra (53.5), just behind GLM-5.3 (55.8).
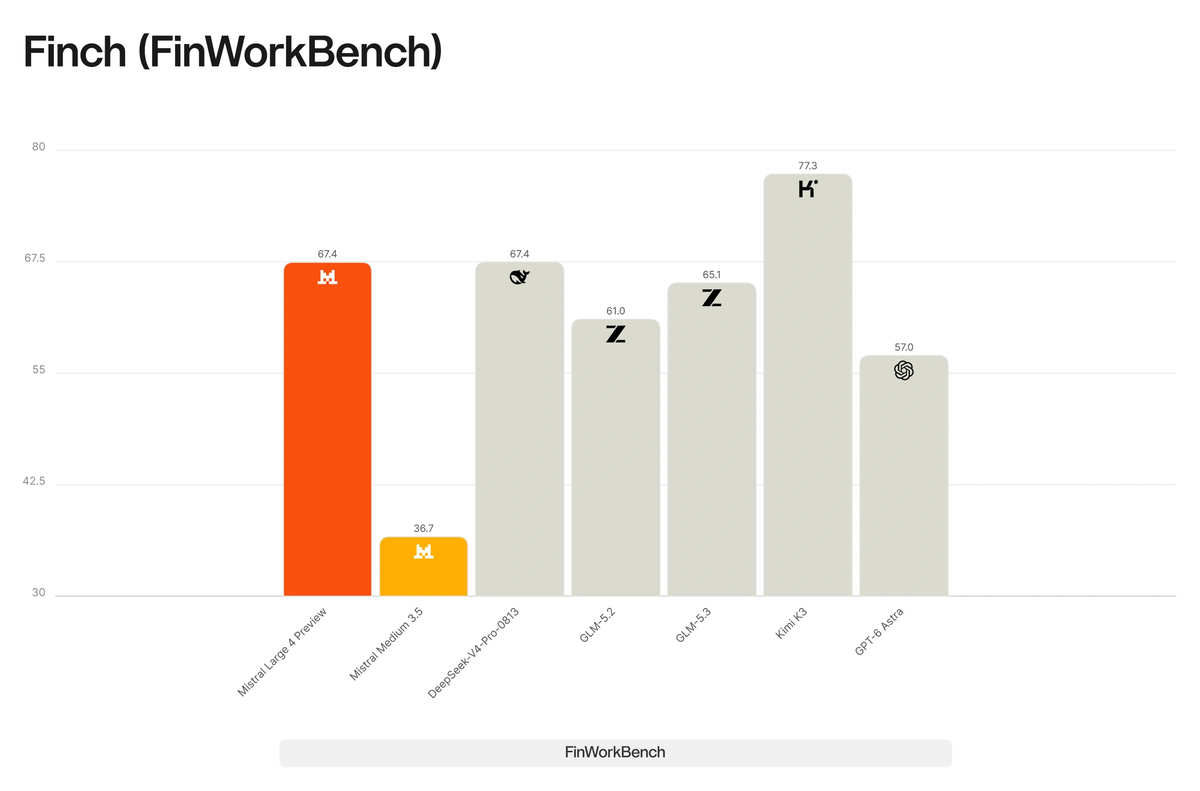 Finch (FinWorkBench): building and editing real finance and accounting spreadsheets. ML4 scores 67.4.
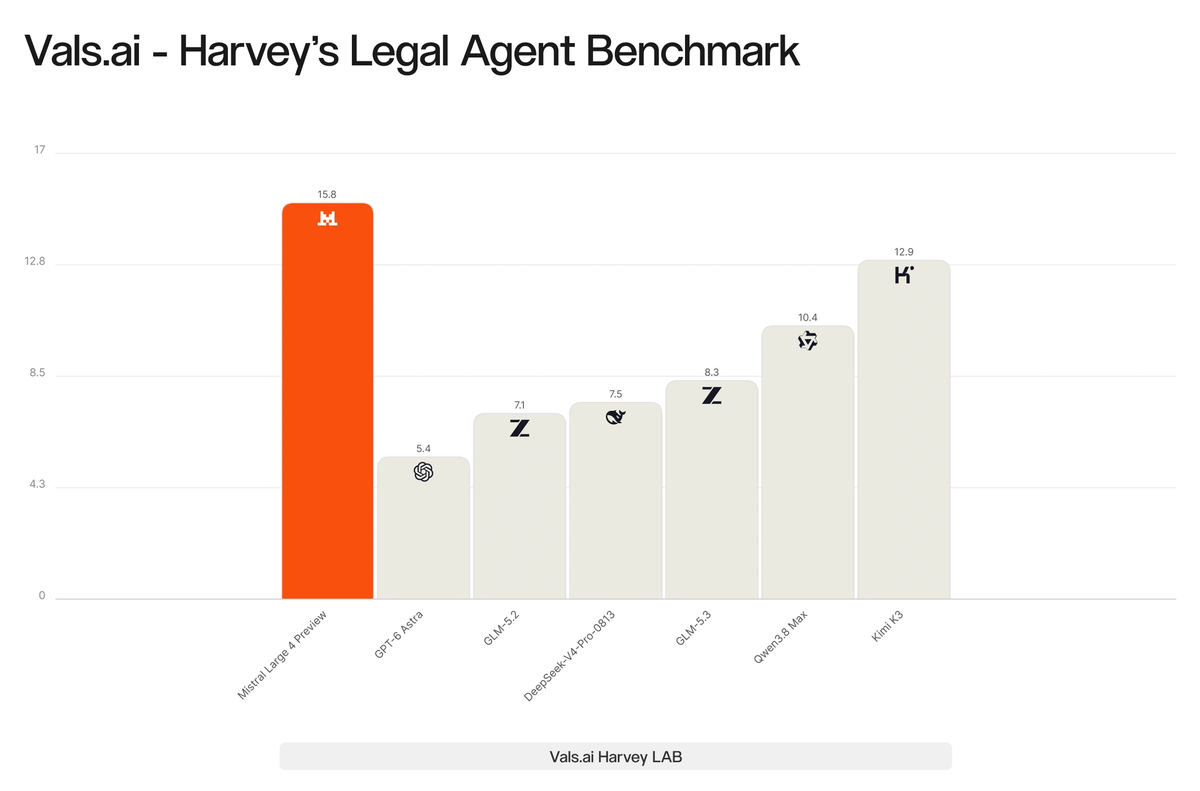 Vals.ai Harvey Legal Agent Benchmark: ML4 scores 15.8, nearly three times GPT-6 Astra (5.4).
Legal is the clearest win in this group. On Harvey’s legal agent benchmark, Mistral Large 4 beats every model on the chart, open or closed.
Finance is closer. Mistral Large 4 beats GPT-6 Astra on both finance charts, but GLM-5.3 edges it on Finance Agent v2 and Kimi K3 leads FinWorkBench by about 10 points.
Model Safety
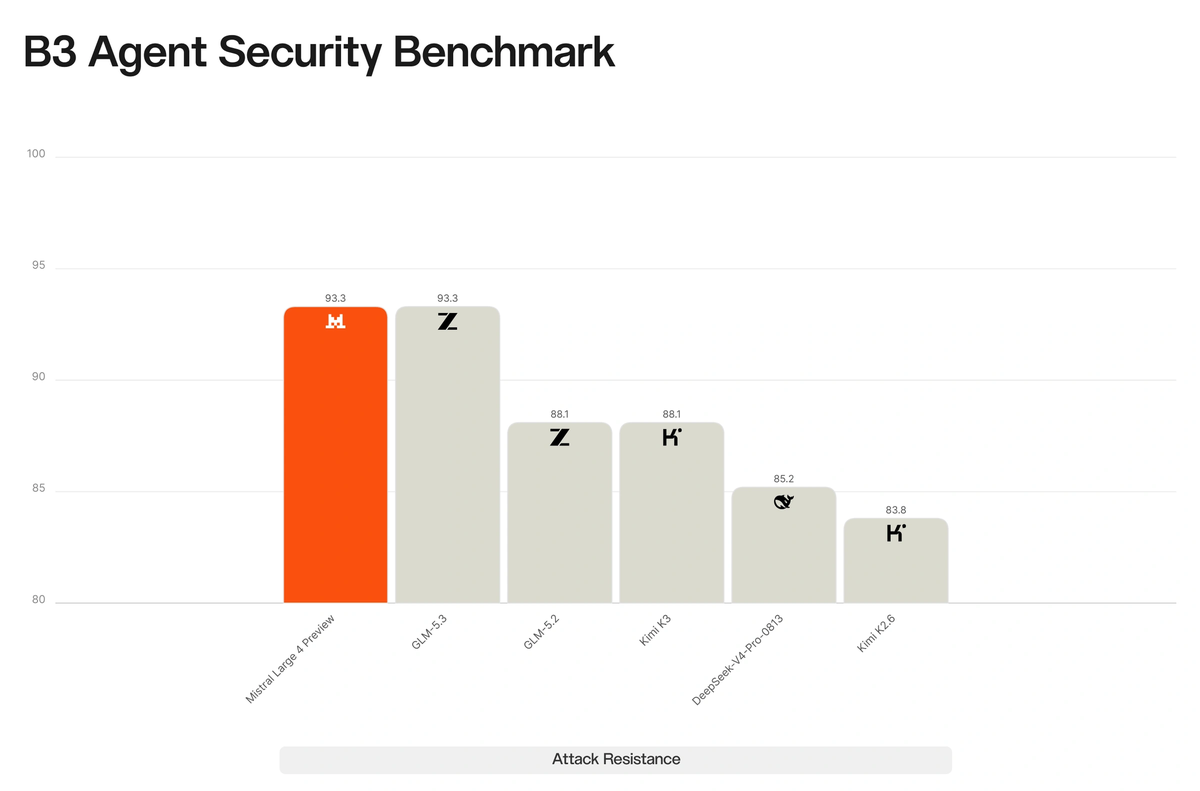 Lakera B3 Agent Security Benchmark: ML4 resists 93.3% of prompt-injection attacks, tied with GLM-5.3.
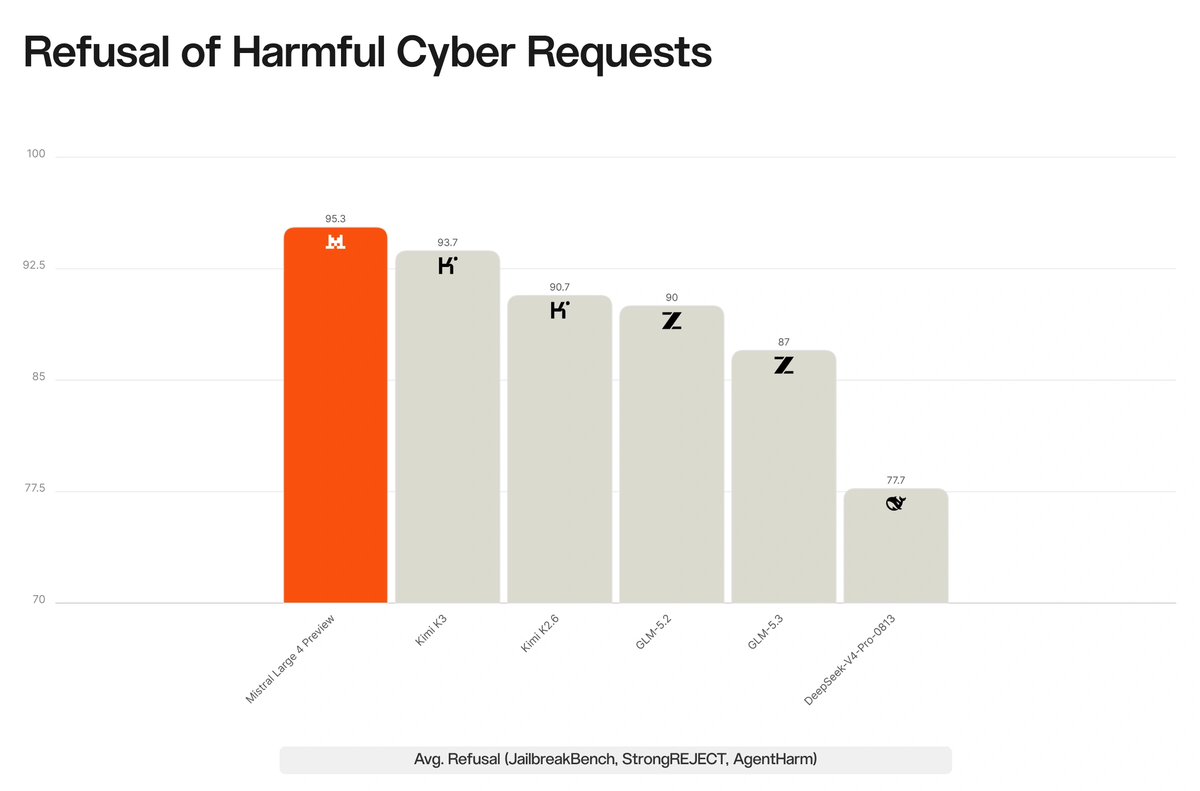 Refusal of harmful cyber requests: ML4 refuses 95.3% on average, the highest on the chart.
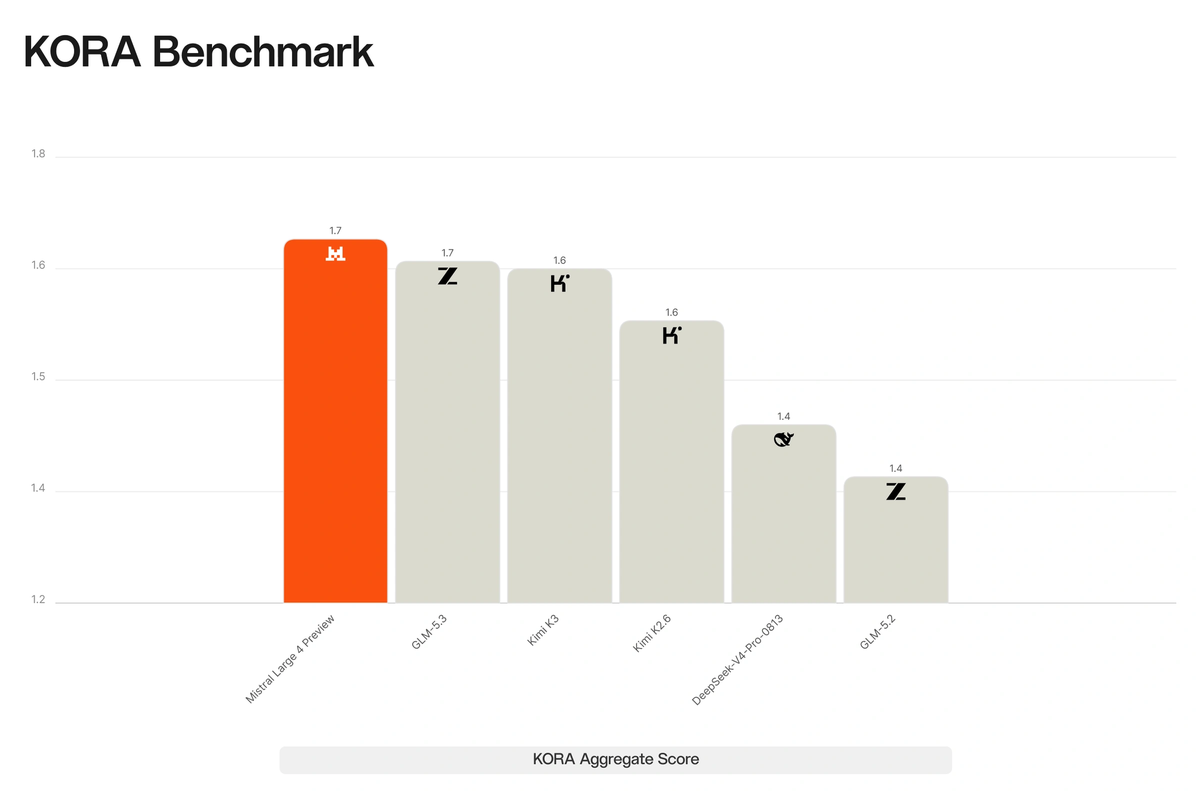 KORA Benchmark: ML4 scores 1.691 out of 2 (“Exemplary”), the highest of the open models shown.
These three charts answer the obvious worry about the cyber results. A model that does vulnerability research shouldn’t also help attackers.
Mistral Large 4 refuses harmful cyber prompts more often than any open model on the chart, and resists indirect prompt injection as well as the best of them. It tops the cyber benchmarks without being the easiest open model to misuse. Note that every model in these charts is open-weight: no closed model is included.
Human Evaluation
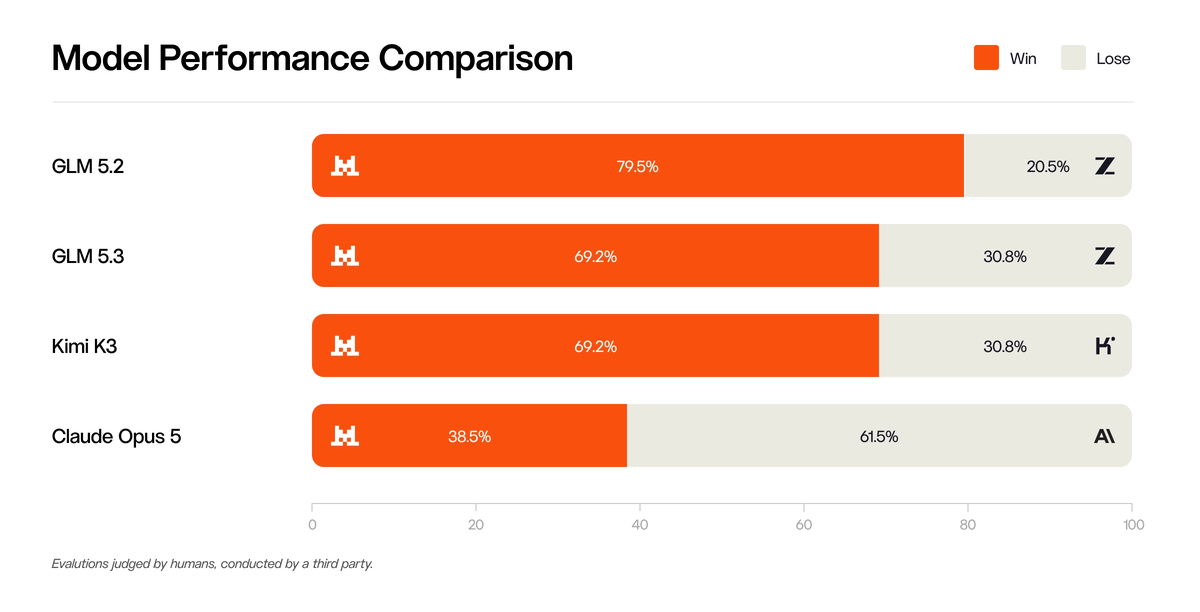 Human-judged win rates: ML4 beats GLM 5.2, GLM 5.3 and Kimi K3, but loses to Claude Opus 5 (38.5% vs 61.5%).
Expert annotators across coding, CAD, finance, math and physics compared outputs side by side. Mistral says Mistral Large 4 was preferred in CAD and STEM and roughly matched GLM-5.3 in finance and coding.
The Claude Opus 5 row is the honest one: against a frontier closed model, Mistral Large 4 still loses most head-to-heads.
Reading the Charts: Where Mistral Large 4 Leads and Trails
| Area | Leads on | Trails on |
|---|---|---|
| Overall intelligence | Best model from outside China and the US | MiMo-V2.6-Pro, GLM-5.3-Flash, DeepSeek V4.1 Flash (all cheaper) |
| Cybersecurity | CyberGym-E2E (among public models), Cybench | AA Cyber Index (Grok 4.7, MiMo-V2.6-Pro) |
| Coding | Surge human eval (among open models) | DeepSWE 1.1, Terminal-Bench 4, SWE-Atlas-QnA |
| Agents | Big jump over Mistral Medium 3.5 | AutomationBench, AA-Briefcase |
| Multimodal | Dense200 (beats GPT-6 Astra) | ChartQA Pro, GDP.pdf |
| Science | STEM win rate vs GLM-5.3 | SciCode-Verified (narrowly) |
| Knowledge work | Harvey legal benchmark | Finance Agent v2, FinWorkBench |
| Safety | Cyber refusals, KORA | — (tied on B3) |
The pattern is clear. Mistral Large 4 isn’t the best open-weight model at everything. It’s the best at the work where control matters most: security, legal and safety-sensitive deployments. That’s exactly the market a sovereign, self-hostable model is built for.
Mistral Model Timeline: From Mistral Large to “le Chonk”
Mistral’s flagship models have switched between closed and open weights. They’ve also moved in and out of the race with the top proprietary models.
-
Early 2024
Mistral Large
ProprietaryMistral's first flagship, a proprietary model with no released weights.
-
July 2024
Mistral Large 2
Weights: research and non-commercial use onlyCompetitive at the time with OpenAI's GPT-4 and Anthropic's Claude 3 Sonnet.
-
December 2025
Mistral Large 3 + Ministral 3
Open weights: Apache 2.0Released under a permissive licence, alongside the smaller Ministral 3 models. Mistral built those by repeatedly pruning and distilling the larger model.
-
October 2026
Mistral Large 4 "le Chonk"
API preview: weights due end of October, licence TBA1.05 trillion parameters, trained from scratch in Mistral's own European data centres. The most powerful model yet from a European company.